Models
16 open models and pipelines, ours and others'. MASHBOX Creature and MASHBOX Voice are free demos for approved companies; the other 14 are available as  .
Text to expressive speech in a voice you describe in plain words.
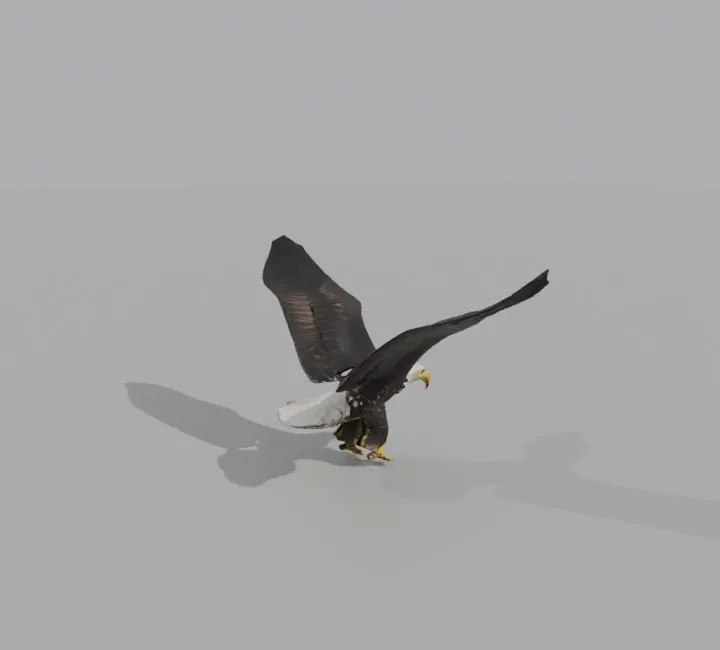
One text prompt to a textured, rigged 3D creature as GLB.
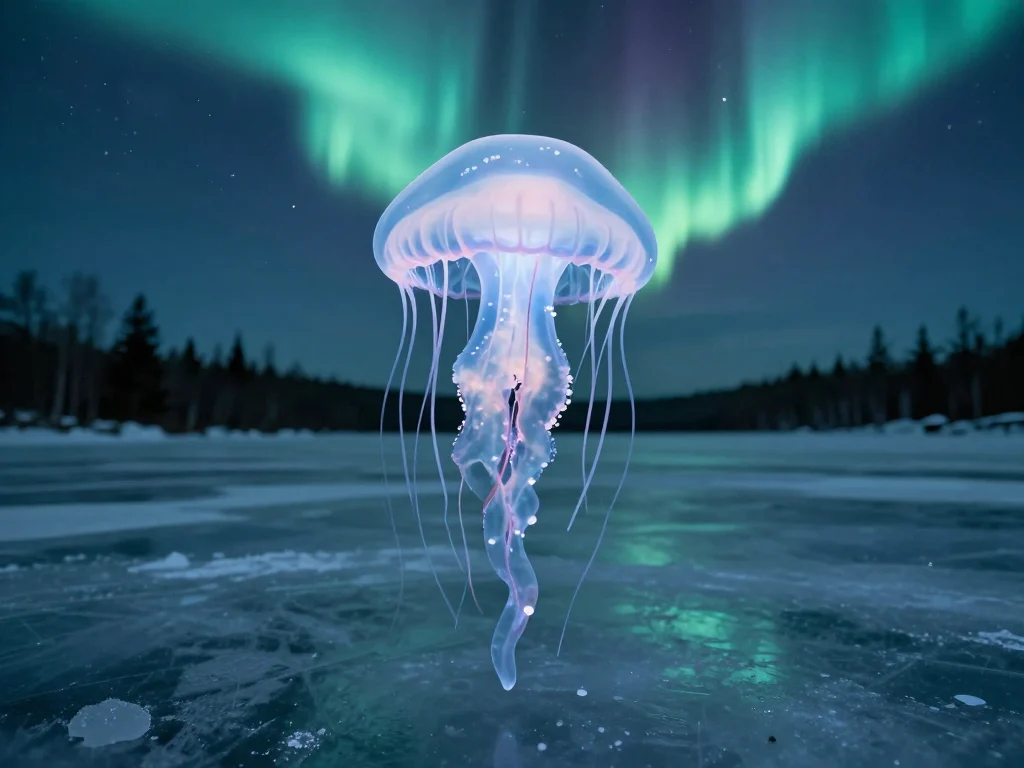
Text to image.
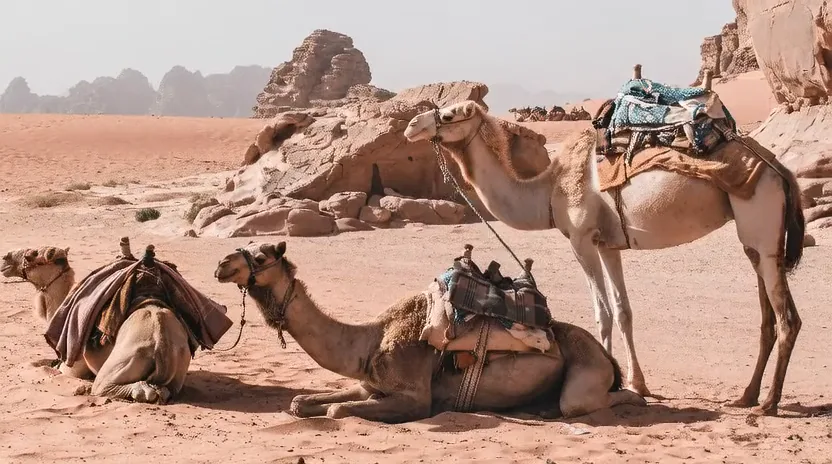
An image and a prompt in, a video clip out.
Chat with streaming, OpenAI-compatible.
Chat, OpenAI-compatible.
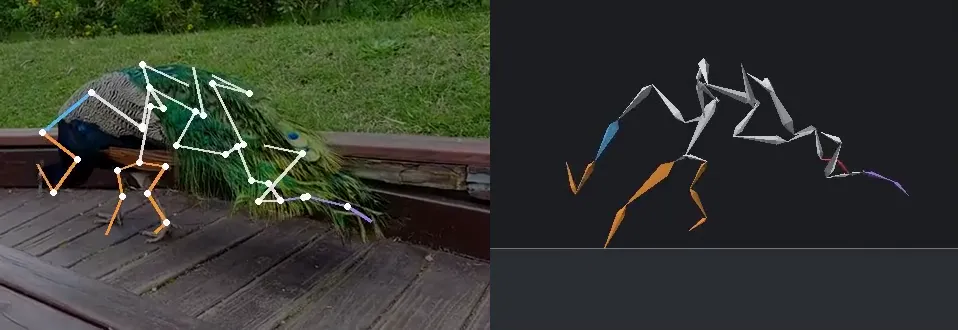
3D point tracks of a moving body in; skeleton, skin and bone motion out as GLB.
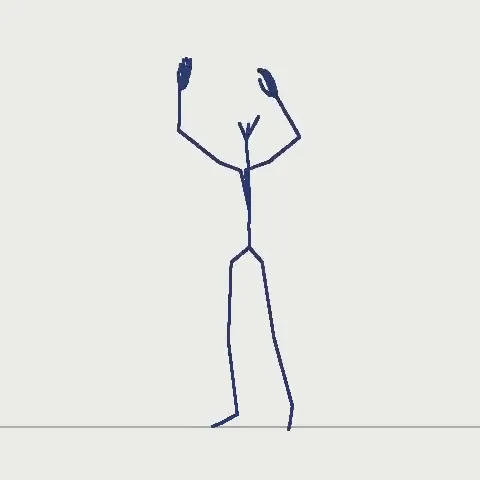
Describe a movement and get a humanoid motion clip.
Text to image.
An image to a textured 3D model.
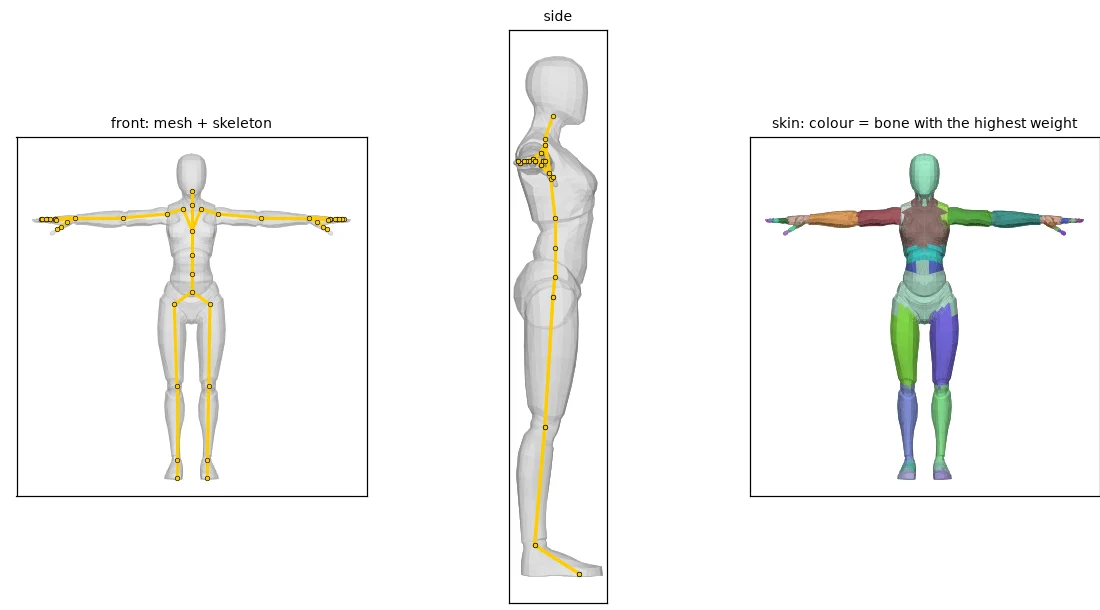
Auto-rig and skin any mesh.
Speech audio to facial animation.
Speech to text, OpenAI-compatible.
Images guided by a pose, depth or edge image.
Image and video upscaling.
An image to a rigged 3D model.
| Model | Kind | Maker | Task |
|---|---|---|---|
| MASHBOX Voice Demo maya1 | Model | MASHBOX Labs, built on Maya1 by Maya Research | Text to speech |
| MASHBOX Creature Demo mbx-creature | Pipeline | MASHBOX Labs | Text to 3D, Rigging |
| Z-Image Turbo z-image-turbo | Model | Tongyi-MAI (Alibaba) | Text to image |
| Wan 2.2 Image to Video wan2.2-i2v-a14b | Model | Wan team (Alibaba) | Image to video |
| Qwen3-30B-A3B qwen3-30b-a3b | Model | Qwen team (Alibaba) | Text to text |
| Llama 3.1 8B Instruct | Model | Meta | Text to text |
| Track2Rig mbx-rig | Model Experimental | MASHBOX Labs | Rigging, Motion |
| MASHBOX Stride mbx-motion | Model | MASHBOX Labs | Motion |
| FLUX.2 [klein] 4B | Model | Black Forest Labs | Text to image |
| TRELLIS.2 | Model | Microsoft | Image to 3D |
| TokenRig | Model | VAST | Rigging |
| Audio2Face-3D | Model | NVIDIA | Motion |
| Granite Speech 4.1 2B | Model | IBM | Speech to text |
| Z-Image ControlNet Union | Model | Alibaba PAI | Text to image |
| Upscaler | Model | Upscaling | |
| AniGen | Model | VAST | Image to 3D, Rigging |