Qwen3-30B-A3B
Model by Qwen team (Alibaba).
Input
text
Output
text
Chat with streaming, OpenAI-compatible.
- What you send
- text
- What you get
- text
Available as a Pack. Write to [email protected].
Qwen3-30B-A3B at 4-bit on one TPU v6e, 1, 10 and 64 users at once
| Users at once | Output tokens a second, all users | p95 wait to first token | Our cost per 1M output tokens |
|---|---|---|---|
| 1 | 301.6 | 317 ms | $2.05 |
| 10 | 409.3 | 954 ms | not computed |
| 64 | 1,906.7 | 5,011 ms | $0.32 |
More models
Z-Image Turbo
Model by Tongyi-MAI (Alibaba)Text to image.
text in, image out
Wan 2.2 Image to Video
Model by Wan team (Alibaba)An image and a prompt in, a video clip out.
image + text in, video out
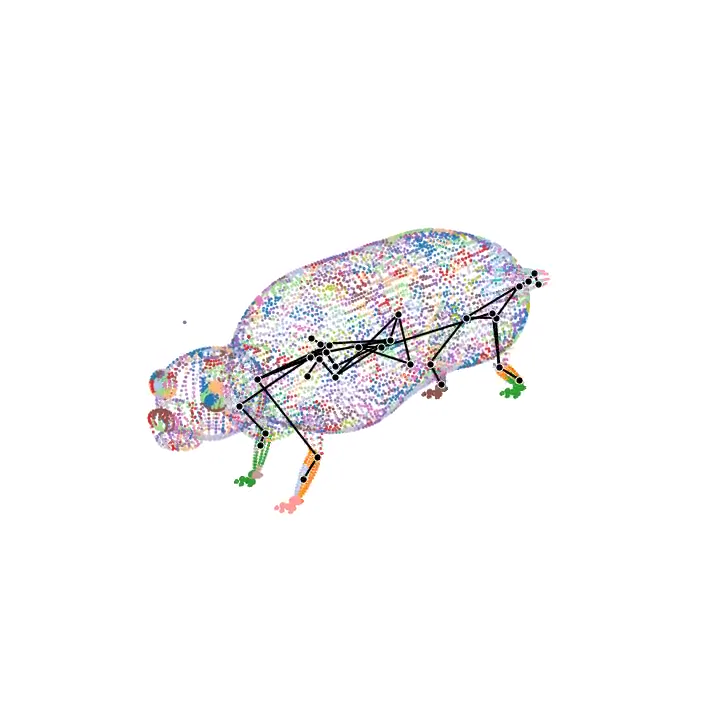
Track2Rig
Model Experimental by MASHBOX Labs3D point tracks of a moving body in; skeleton, skin and bone motion out as GLB.
3D point tracks in, skeleton, skin and motion (GLB) out
MASHBOX VoiceRequest access
Model by MASHBOX LabsText to expressive speech in a voice you describe in plain words. Built on Maya1 by Maya Research.
text in, speech out