

MASHBOX Labs

MASHBOX Labs makes open models run faster and cheaper on TPUs and accelerated hardware, as well as exploring the future of the intersection of AI and gaming.


MASHBOX Steer
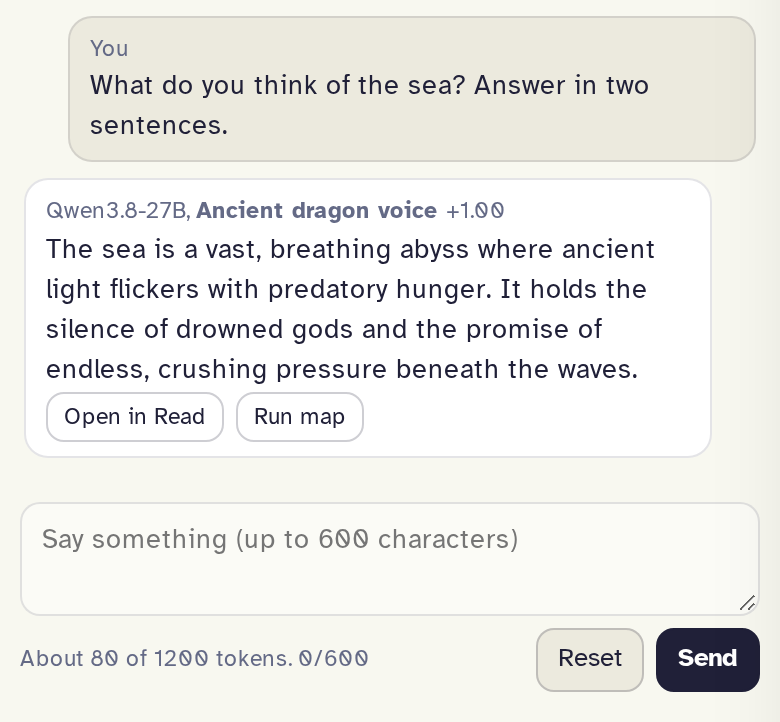

See which neurons fire as a model reads your text, then turn them up or down and watch its replies change.
In MASHBOX for Mac
Models we run
38 models and files run in mashbox: 5 MASHBOX builds and 33 GGUF files of 20 models.
Qwen3.8-27B
By Qwen, 27B parameters. Our BQ8_R build on one TPU v6e-1.
Hy-Nomas world model
Tencent Hunyuan's open video world model: text and movement keys in, video out, on a TPU v6e-4.
GGUF files that run in our engine
GGUF files from other publishers, run as they are. Level and Runs on say how far each file has been checked; a speed shows only where we measured one on a chip. Each speed in these tables is from a short check of that one file. The Qwen3.8-27B numbers above are for our BQ8_R build.
0bserverx 1 fileQwen3.8-27B
| Model | GGUF file | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|
Qwen3.8-27B by Qwen | Qwen3.8-27B-Heretic-Q4_K_M.gguf 16.55 GB | Q4_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 39.28 tok/s, steady decode, 1 user, on TPU v6e-1 |
bartowski 7 filesFalcon3-1B-Instruct, Llama-3.2-1B-Instruct, Llama-3.2-3B-Instruct, Qwen2.5-0.5B-Instruct, Qwen2.5-1.5B-Instruct, Qwen2.5-7B-Instruct
| Model | GGUF file | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|
Falcon3-1B-Instruct by Technology Innovation Institute | Q8_0 | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 581.7 tok/s, steady decode, 1 user, on TPU v6e-1 | |
Llama-3.2-1B-Instruct by Meta | Q4_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 472.41 tok/s, steady decode, 1 user, on TPU v6e-1 | |
Llama-3.2-3B-Instruct by Meta | IQ4_XS | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 257.13 tok/s, steady decode, 1 user, on TPU v6e-1 | |
Qwen2.5-0.5B-Instruct by Qwen | Q4_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 325.25 tok/s, steady decode, 1 user, on TPU v6e-1 | |
Qwen2.5-1.5B-Instruct by Qwen | Q4_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 212.09 tok/s, steady decode, 1 user, on TPU v6e-1 | |
Qwen2.5-1.5B-Instruct by Qwen | Q5_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 201.71 tok/s, steady decode, 1 user, on TPU v6e-1 | |
Qwen2.5-7B-Instruct by Qwen | Q4_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 119.27 tok/s, steady decode, 1 user, on TPU v6e-1 |
byteshape 1 fileQwen3.8-27B
| Model | GGUF file | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|
Qwen3.8-27B by Qwen | IQ2_XXS | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 11.78 tok/s, steady decode, 1 user, on TPU v6e-1 |
cdiamond 1 fileQwen3.8-27B
| Model | GGUF file | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|
Qwen3.8-27B by Qwen | MTP | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 13.56 tok/s, steady decode, 1 user, on TPU v6e-1 |
DavidAU 2 filesQwen3.5-9B-The-Defiant-Fable-Uncensored-Heretic-NEO-IMATRIX-MAX-MTP, Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NM-DAU
| Model | GGUF file | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|
Qwen3.5-9B-The-Defiant-Fable-Uncensored-Heretic-NEO-IMATRIX-MAX-MTP by DavidAU | Q4_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 108.8 tok/s, steady decode, 1 user, on TPU v6e-1 | |
Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NM-DAU by DavidAU | Q4_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 39.21 tok/s, steady decode, 1 user, on TPU v6e-1 |
ggml-org 1 fileQwen3.8-27B
| Model | GGUF file | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|
Qwen3.8-27B by Qwen | Qwen3.8-27B-Q4_K_M.gguf 18.97 GB | Q4_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 41.48 tok/s, steady decode, 1 user, on TPU v6e-1 |
HauhauCS 1 fileQwen3.8-27B
| Model | GGUF file | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|
Qwen3.8-27B by Qwen | Q4_K_P | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 35.5 tok/s, steady decode, 1 user, on TPU v6e-1 |
huihui-ai 1 fileQwen3.8-27B
| Model | GGUF file | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|
Qwen3.8-27B by Qwen | Q4_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 32.82 tok/s, steady decode, 1 user, on TPU v6e-1 |
ibm-granite 1 filegranite-3.3-2b-instruct
| Model | GGUF file | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|
granite-3.3-2b-instruct by IBM | Q4_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 238.1 tok/s, steady decode, 1 user, on TPU v6e-1 |
JonathanColetti 1 fileQwen3.8-27B
| Model | GGUF file | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|
Qwen3.8-27B by Qwen | Q4_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 39.12 tok/s, steady decode, 1 user, on TPU v6e-1 |
LGAI-EXAONE 1 fileEXAONE-3.5-2.4B-Instruct
| Model | GGUF file | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|
EXAONE-3.5-2.4B-Instruct by LG AI Research | Q4_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 297.52 tok/s, steady decode, 1 user, on TPU v6e-1 |
lmstudio-community 2 filesQwen3.5-9B, Qwen3.8-27B
| Model | GGUF file | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|
Qwen3.5-9B by Qwen | Qwen3.5-9B-Q4_K_M.gguf 5.63 GB | Q4_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 111.73 tok/s, steady decode, 1 user, on TPU v6e-1 |
Qwen3.8-27B by Qwen | Qwen3.8-27B-Q4_K_M.gguf 16.81 GB | Q4_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 39.08 tok/s, steady decode, 1 user, on TPU v6e-1 |
peculiar-ragdoll 1 fileQwen3.8-27B
| Model | GGUF file | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|
Qwen3.8-27B by Qwen | Dirk-Qwen3.8-27B-UD-Q4_K_M.gguf 16.46 GB | Q4_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 32.08 tok/s, steady decode, 1 user, on TPU v6e-1 |
Qwen 5 filesQwen2.5-0.5B-Instruct, Qwen2.5-1.5B-Instruct, Qwen2.5-Coder-1.5B-Instruct, Qwen3-14B, Qwen3-4B
| Model | GGUF file | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|
Qwen2.5-0.5B-Instruct by Qwen | q4_k_m | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 326.75 tok/s, steady decode, 1 user, on TPU v6e-1 | |
Qwen2.5-1.5B-Instruct by Qwen | q4_k_m | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 211.71 tok/s, steady decode, 1 user, on TPU v6e-1 | |
Qwen2.5-Coder-1.5B-Instruct by Qwen | q4_k_m | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 210.52 tok/s, steady decode, 1 user, on TPU v6e-1 | |
Qwen3-14B by Qwen | Q4_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 63.7 tok/s, steady decode, 1 user, on TPU v6e-1 | |
Qwen3-4B by Qwen | Qwen3-4B-Q4_K_M.gguf 2.5 GB | Q4_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 166.3 tok/s, steady decode, 1 user, on TPU v6e-1 |
unsloth 7 filesgemma-3-1b-it, Qwen3-0.6B, Qwen3-1.7B, Qwen3-4B-Instruct-2507, Qwen3.5-4B, Qwen3.5-9B, Qwen3.8-27B
| Model | GGUF file | Quant | Level | Runs on | Speed |
|---|---|---|---|---|---|
gemma-3-1b-it by Google DeepMind | gemma-3-1b-it-Q4_K_M.gguf 0.81 GB | Q4_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 212.82 tok/s, steady decode, 1 user, on TPU v6e-1 |
Qwen3-0.6B by Qwen | Qwen3-0.6B-Q8_0.gguf 0.64 GB | Q8_0 | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 416.18 tok/s, steady decode, 1 user, on TPU v6e-1 |
Qwen3-1.7B by Qwen | Qwen3-1.7B-Q4_0.gguf 1.06 GB | Q4_0 | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 239.61 tok/s, steady decode, 1 user, on TPU v6e-1 |
Qwen3-4B-Instruct-2507 by Qwen | Q4_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 166.67 tok/s, steady decode, 1 user, on TPU v6e-1 | |
Qwen3.5-4B by Qwen | Qwen3.5-4B-Q4_K_M.gguf 2.74 GB | Q4_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 171.83 tok/s, steady decode, 1 user, on TPU v6e-1 |
Qwen3.5-9B by Qwen | Qwen3.5-9B-Q4_K_M.gguf 5.68 GB | Q4_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 112.04 tok/s, steady decode, 1 user, on TPU v6e-1 |
Qwen3.8-27B by Qwen | Qwen3.8-27B-UD-Q4_K_M.gguf 16.46 GB | Q4_K_M | Quick check Runs on TPU v6e-1 with the engine's TPU kernels: short check against llama.cpp (4 prompts x 32 tokens) | TPU v6e-1 | 32.36 tok/s, steady decode, 1 user, on TPU v6e-1 |
Track2Rig Experimental
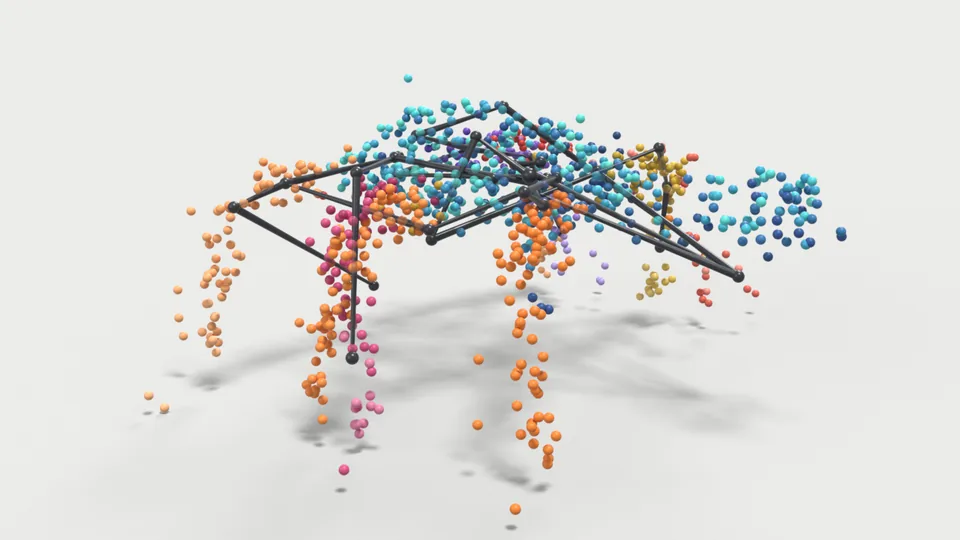
3D point tracks in; skeleton, skin and bone motion out as GLB. Error on our test set, not on this clip: 0.784%, against 0.915% for SSDR.
Start here
From a new Google account to an open model answering on your own TPU, then to your coding agent.
MASHBOX Labs onMASHBOX Labs on
Latest release: mashbox 0.1.15. Open source
Install mashbox
curl -fsSL https://mashbox.gg/install.sh | sh On your Mac or Linux machine, without sudo.
Set up Google Cloud
Make a Google Cloud project with billing and the TPU API turned on.
Bring up a TPU and run a model
mashbox tpu up qwen3-8-27bIt shows the price and asks before it creates anything.
Connect your coding agent
mashbox tpu up qwen3-8-27b --agents --restartClaude Code, Codex and Pi can use the model you serve as their LLM.
Read the docs
The FAQ, troubleshooting, which TPU to pick, the licences, and an llms.txt your coding agent can read.
Earlier results
- 87.4 fpsEdenLive 5B real-time video on one TPU v6e; one H100: 73.52 (EdenLive's figure)
- 2.10xvLLM TPU 0.31's throughput: Llama 3.2 1B, 256 conversations, same TPU v6e
- 180.4 tok/sMiMo-V2.6-Flash (309B, 15B active) on one TPU v5p-8 slice, 4 chips; 1.22x the fastest listed provider
- 249.9 tok/sLlama 2 7B 4-bit, llama.cpp on one TPU v6e; RTX 4090 row: 188.96
AI and gaming
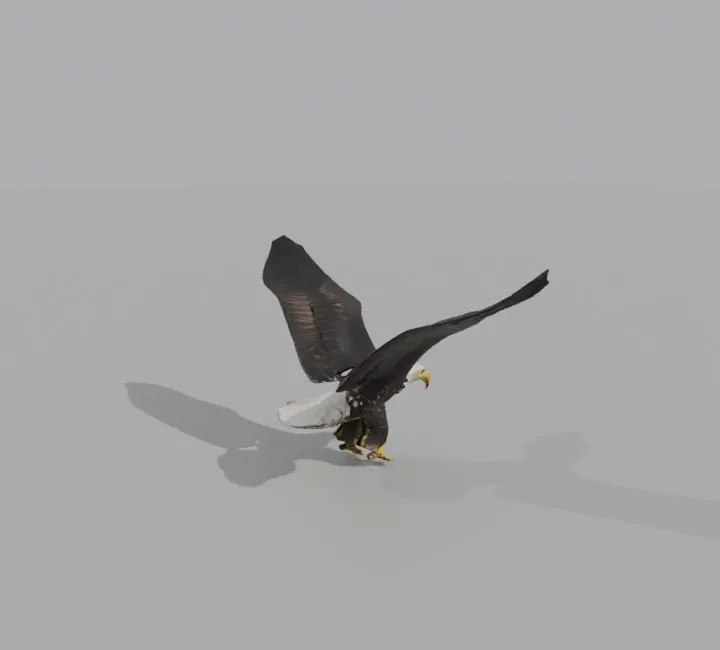
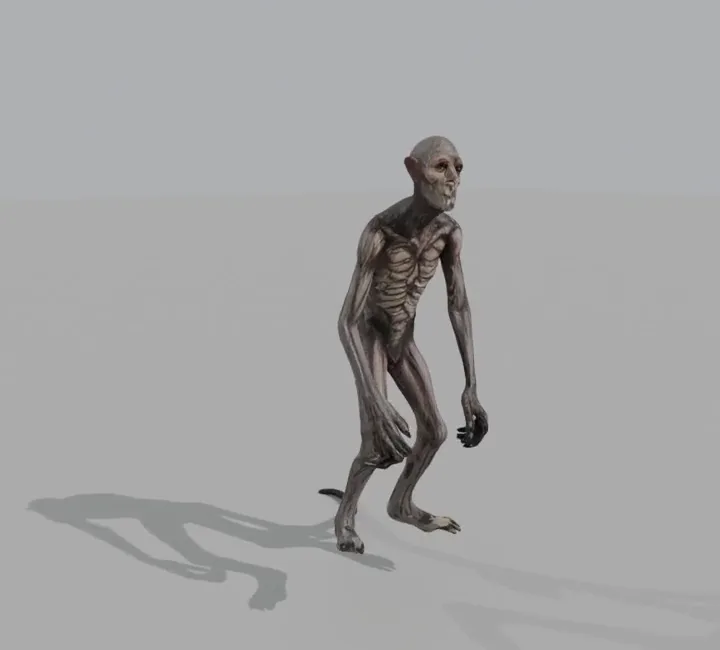
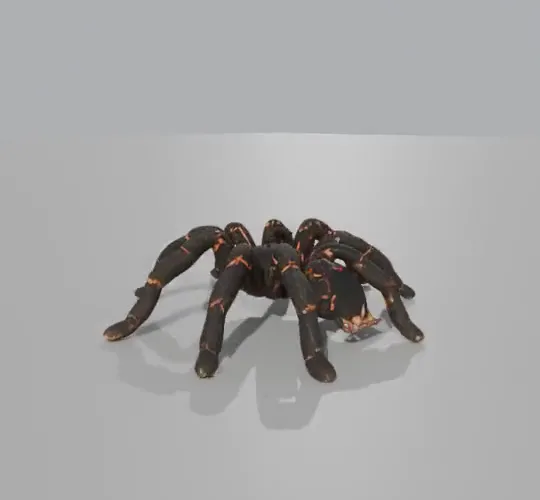
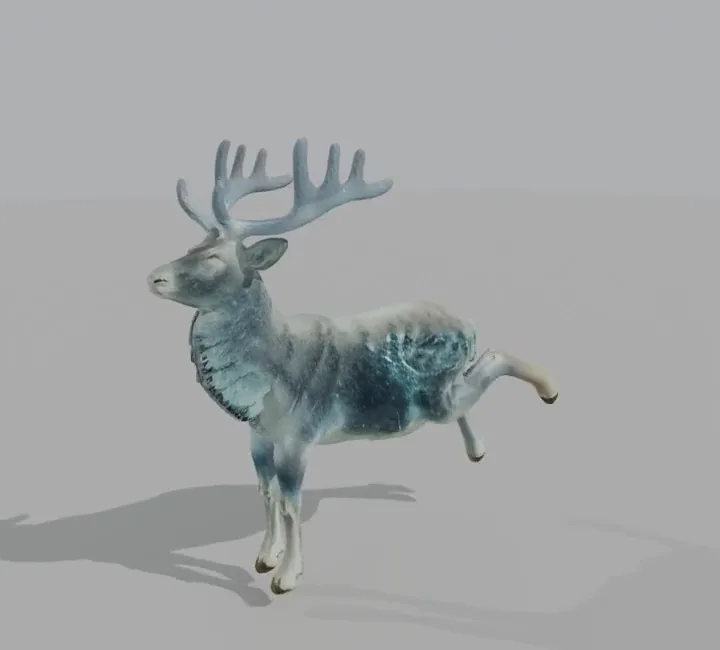
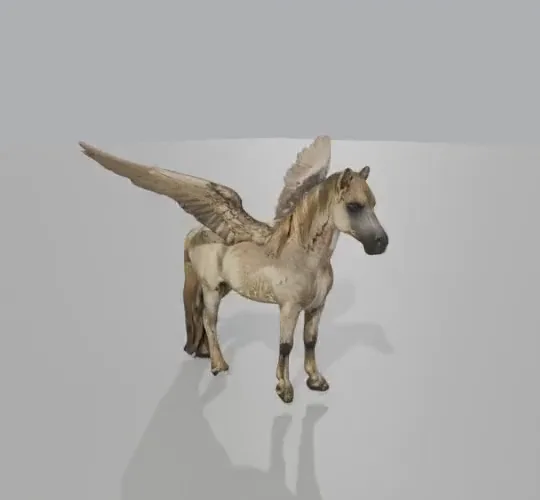
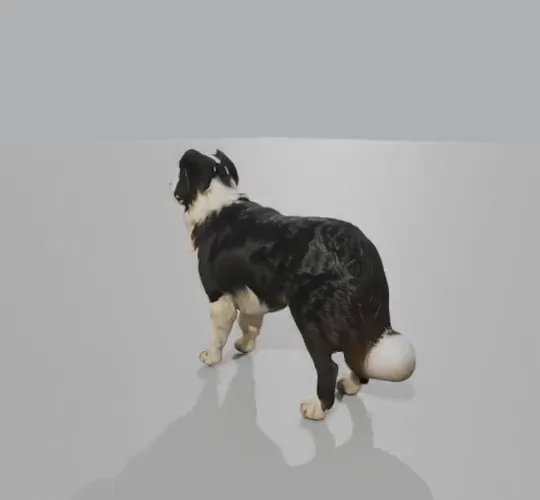
3D creatures from a text prompt, motion for any creature's skeleton and voices from a plain description, running on TPU, plus rigs recovered from 3D point tracks.
Rigged, animated 3D creatures
Live demoUp to 200 characters of prompt in. One GLB out, rigged and textured. Each creature comes with its own motion clips. Pick one and drag to turn the model.
- 305 s from click to downloads for a full text-to-rigged creature in the live demo.
- Chip cost per creature for the first job on a new TPU v6e chip, with the models loading: $0.065 at the Google Cloud spot list price, $0.318 at the on-demand list price.
Styles: realistic (default), anime, cartoon, storybook, horror. POST /v1/creatures.
For businesses
What we sell
 3D
 Managed